- الصفحة الرئيسية /
- الكتب /
- الكمبيوتر والتكنولوجيا /
- علوم الكمبيوتر /
- AI & Machine Learning /
- Intelligence & Semantics /
- Reinforcement Learning from Human Feedback: L...
0 ratings


منتج #:
248983336
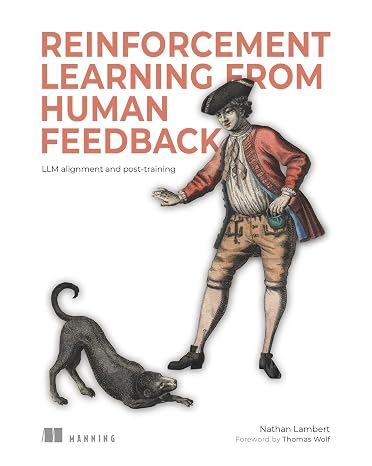
Reinforcement Learning from Human Feedback: LLM alignment and post-training
89% من المشترين سيوصون بهذا المنتج لصديق
منتج #:
248983336
OMR 32
تفاصيل السعر
باستثناء رسوم الشحن والجمارك ( سيتم احتساب رسوم الشحن والجمارك عند إتمام الشراء )
*سيتم استيراد جميع العناصر من أمريكا
0 ratings
اكتب رأيك
متوفر فى المخزون
 مستورد من متجر USA
كمية:
اطلب الآن واحصل عليه حول الإثنين, أكتوبر 26
معاملة آمنة
تعمل يوباي جاهدة لحماية أمنك وخصوصيتك. يضمن نظام أمان الدفع المتقدم لدينا السرية من خلال تشفير معلوماتك أثناء النقل باستخدام بروتوكولات AES (معايير التشفير المتقدمة) وSSL (طبقة المنافذ الآمنة). تفاصيل الدفع الخاصة بك آمنة بنسبة %100 لأننا لا نشارك تفاصيل الدفع الخاصة بك مع بائعين تابعين لجهات خارجية
أفضل شركائنا اللوجستيين


Reinforcement Learning from Human Feedback helps you understand one of the most important techniques behind modern LLM alignment and post-training.

شحن
سريع

استرجاع
مجاني*

تغليف آمن

منتجات أصلية %100

الامتثال لمعيار PCI DSS

حاصل على شهادة ISO 27001
Note: Step Down Voltage Transformer required for using electronics products of أمريكا store (110-120). Recommended power converters اشتري الآن.


أبرز ما يلفت الانتباه
Human-Centric Training
Utilizes human feedback to fine-tune models, ensuring that AI aligns closely with user values and preferences, enhancing satisfaction and real-world applicability.
Post-Training Optimization
Offers advanced techniques for model alignment after initial training, ensuring continual improvement and adaptation, which outperforms static models in dynamic environments.
Enhanced Safety Measures
Integrates rigorous safety protocols to minimize risks associated with AI decision-making, providing users and developers with greater confidence in AI deployment.
تفاصيل المنتج
- Get the eBook free when you register your print book at Manning.A masterful synthesis of the field’s intellectual roots and its practical tools.”—Saurabh Sawant, MicrosoftReinforcement Learning from Human Feedback: LLM alignment and post-training helps you understand how modern AI models can be adapted to better match the needs and expectations of their users. Rather than surveying the vast field of reinforcement learning, elite AI researcher Nathan Lambert concentrates exclusively on RLHF and its immediate importance to post-training generative AI models.This compact book gets right to the point. Early chapters establish the training overview, explain instruction fine-tuning, and build reliable reward models. The middle chapters transition into the heart of alignment, exploring core policy gradient algorithms, Direct Preference Optimization (DPO), and inference-time scaling. Later chapters tackle the messy reality of data, guiding you through preference data collection, synthetic data generation, and the nuances of function calling.As you go, you will see how these post-training methods actually work, including their unique compute costs and latency trade-offs. You will explore common failure modes, such as qualitative over-optimization, reward hacking, and the unreliability of external evaluation comparisons. Difficult concepts like KL regularization, proximal policy optimization, and generative reward modeling are clarified with hands-on experiments.Reinforcement Learning from Human Feedback avoids irrelevant academic details in favor of immediate, practical value. Everything author Nathan Lambert includes appears because a modern RLHF project requires it. He skillfully explains complex post-training pipelines by making every detail concrete, connecting isolated abstractions directly to the goal of making models safer, smarter, and perfectly tuned to a desired style.The book’s seventeen short chapters lay out the core material, while supplements like vocabulary definitions, compute cost management, evaluation variance, and training performance tracking appear in handy appendixes. The result is a logically flowing book that remains highly navigable and technically deep without getting bogged down in unnecessary theory.The book covers• Core RLHF implementations and Direct Alignment Algorithms• Building robust preference and synthetic data pipelines• Evaluating models and crafting specific AI personasAbout the readerFor established engineers, AI scientists, and students trying to get a practical foothold in AI model alignment.About the authorDr. Nathan Lambert is a leading AI researcher known for leading post-training at the Allen Institute for AI. With previous experience at HuggingFace, DeepMind, and Meta, he is a passionate advocate for open models. His work focuses on increasing access to, and the understanding of, AI technology—empowering readers to contribute to the advancement of AI outside closed corporate labs.Table of ContentsPart 11 Introduction2 A tiny history of RLHF3 Training overviewPart 24 Instruction fine-tuning5 Reward modeling6 Reinforcement learning7 Reasoning and inference-time scaling8 Direct-alignment algorithms9 Rejection samplingPart 310 The nature of preferences11 Preference data12 Synthetic dataPart 413 Tool use and function calling14 Over-optimization15 Regularization16 Evaluation17 Crafting model character and productsA DefinitionsB Beyond “just style”C Practical Issues
| الناشر | Manning Publications |
| تاريخ النشر | 4 أغسطس 2026 |
| اللغة | إنجليزي |
| طول الطباعة | 312 صفحة |
| ISBN-10 | 1633434303 |
| ISBN-13 | 978-1633434301 |
| وزن العنصر | 8.5 أونصة (240.98 جرام) |
| الأبعاد | 7.38 x 0.71 x 9.25 inches (18.7 x 1.8 x 23.5 cm) |
وصف المنتج
هل لديك أي استفسار؟ تحدث معنا
أسئلة العملاء & الإجابات
-
سؤال:
كيف تتسوق Reinforcement Learning from Human Feedback: LLM عبر الانترنت من يوباى?
إجابه: من السهل التسوق في Reinforcement Learning from Human Feedback: LLM عبر الإنترنت من يوباي. كل ما عليك فعله هو البحث عن المنتج واختيار طريقة الشحن الخاصة بك أثناء الدفع وسيتم توصيله الى عنوانك -
سؤال:
هل Reinforcement Learning from Human Feedback: LLM متوفر للتسوق عبر الإنترنت في Oman؟
إجابه: نعم ، في يوباي Oman هذا المنتج متاح لك للتسوق بسعر مناسب. Reinforcement Learning from Human Feedback: LLM غير متوفر محليًا ولكن يمكنك الوثوق بنا بخدماتنا للشحن السريع. -
سؤال:
كم من الوقت يستغرق الحصول على المنتج بعد تقديم الطلب؟
إجابه: يختلف وقت تسليم المنتج الذي طلبته حسب ما طلبته وطريقة الشحن التي اخترتها. يتم ذكر وقت التسليم المقدر أثناء عملية الدفع ، لذا كن مرتاحًا أثناء التسوق.
Intelligence & Semantics Editorial Review
لم يتم العثور على مراجعات تحريرية
مراجعات العملاء وتقييماتهم
14 تقييمات العملاء
-
5 نجمة
77%
-
4 نجمة
0%
-
3 نجمة
0%
-
2 نجمة
12%
-
1 نجمة
11%
أضف تقييم لهذا المنتج
شارك أفكارك مع عملاء آخرين
منصة موثوقة وثقة كاملة للمشتري
JK
Jasmin
مشتري موثّق
“Great products and very good service: very easy and very fast international delivery.”
9 September 2026 · عبر Trustpilot
AG
Anke
مشتري موثّق
“Wonderful online shopping experience, smooth transaction from the start. Payment method works conveniently and delivery is unexpectedly fast and reliable. You go the extra mile for service. What makes this even more amazing, you deliver to Namibia. I will remain a happy Ubuy customer and will increase my purchases for sure! Thank you!”
10 September 2026 · عبر Trustpilot
H
Hazel
مشتري موثّق
“Very easy to find the products what you need, and so fast delivery, that’s why I highly recommended to others costumers to used ubuy.”
10 September 2026 · عبر Trustpilot
O
Opaleye
مشتري موثّق
“I received exactly what I ordered I was skeptical about your site because that was my first time to order. But the order came timely and neatly packaged. I was not disappointed. Thank you.”
11 September 2026 · عبر Trustpilot
AC
Adele
مشتري موثّق
“Easy to find and order what you want on the website. Delivery is quick to the UK”
8 September 2026 · عبر Trustpilot
لماذا تتسوق معنا؟
الخروج الآمن
شحن عالمي
إسترجاع سهل
منتجات أصلية
تاريخ سعر المنتج
معلومات مهمة
- القيود: بالنسبة للمنتجات التي يتم شحنها دولياً، يُرجى ملاحظة أن أي ضمان من الشركة المصنعة قد لا يكون صالحاً؛ قد لا تتوفر خيارات خدمة الشركة المصنعة؛ قد لا تكون أدلة المنتج والتعليمات وتحذيرات السلامة مكتوبة بلغة بلد المقصد؛ قد لا يتم تصميم المنتجات (والمواد المصاحبة لها) وفقاً لمعايير بلد الوجهة والمواصفات ومتطلبات الملصقات؛ وقد لا تتوافق المنتجات مع الجهد الكهربي المستخدم في بلد الوجهة والمعايير الكهربائية الأخرى (تتطلب استخدام محوّل كهربي أو جهاز تحويل إذا كان ذلك مناسباً). المستلم مسؤول عن ضمان إمكانية استيراد المنتج بشكل قانوني إلى بلد الوجهة. عند الطلب من يوباي أو الشركات التابعة لها، يكون المستلم هو المستورد المسجل ويجب أن يلتزم بجميع القوانين واللوائح الخاصة ببلد الوجهة.
- ليست كل المنتجات المدرجة على يوباي معروضة للبيع، لأن يوباي هو محرك بحث عالمي. المنتجات تخضع للوائح التصدير / التجارة.
OMR 32
اطلب الآن واحصل عليه حول الإثنين, أكتوبر 26
هذا المنتج غير ممنوع في بلدي. (الرجاء الضغط على الرابط أعلاه إذا لم يكن هذا المنتج ممنوعاً في بلدك ، لذلك سيقوم فريقنا بمراجعته والسماح به.)
كمية:
معاملة آمنة
نوفر لك مدفوعات مشفّرة، وحماية متكاملة للمشتري، مع الالتزام بمعايير PCI DSS وشهادة ISO 27001:2022 لضمان أعلى مستويات الأمان في كل عملية شراء.
أفضل شركائنا اللوجستيين
أسرع توصيل عبر الحدود
المميزات والفوائد
- Gain insights into aligning AI models with human preferences.
- Practical guidance on reinforcement learning and its components.
- Focus on RLHF's impact on generative AI models.
- Hands-on experiments clarify complex concepts.
- Avoids unnecessary academic details for immediate application.
- Ideal for AI engineers, researchers, and technical leaders.
ضمان Ubuy
تسوّق بثقة مع منتجات أصلية %100، ومدفوعات آمنة متوافقة مع معيار PCI DSS، وحماية بيانات معتمدة وفق ISO 27001، وشحن دولي سريع، وإرجاع مجاني*، وتغليف آمن لكل طلب.